

Welcome back to Better Know a Dataset!
In this post, we explore posts from an online consultation board where thousands of Korean men—completely anonymous—ask strangers for advice on everything from "my girlfriend is mad at me" to "should I buy Bitcoin?" to "how do I quit my job?"
Introduction
Millions of people now treat ChatGPT as a therapist. They tell it things they won't tell their friends, their partners, their actual therapists. But this isn't new: it turns out that Korean men have been doing it for over a decade, just not with AI.
DogDrip.net is one of South Korea's largest online communities, which I’ll explore in this post. Korea has many online communities, but DogDrip’s consultation board is unusual in two ways. First it’s fully anonymous, and second it’s large enough to generate statistical patterns. It’s also specifically designed for advice-seeking, which makes the posts more confessional than the typical forum rant.
Data
I scraped about 355,000 posts from the anonymous consultation board (고민게시판), spanning late 2014 to early 2026. The site's user base is 82% male, so this is really a window into Korean men's concerns, not Korean concerns broadly.
Here’s an example of a post (original on the left; English translation by ChatGPT on the right):
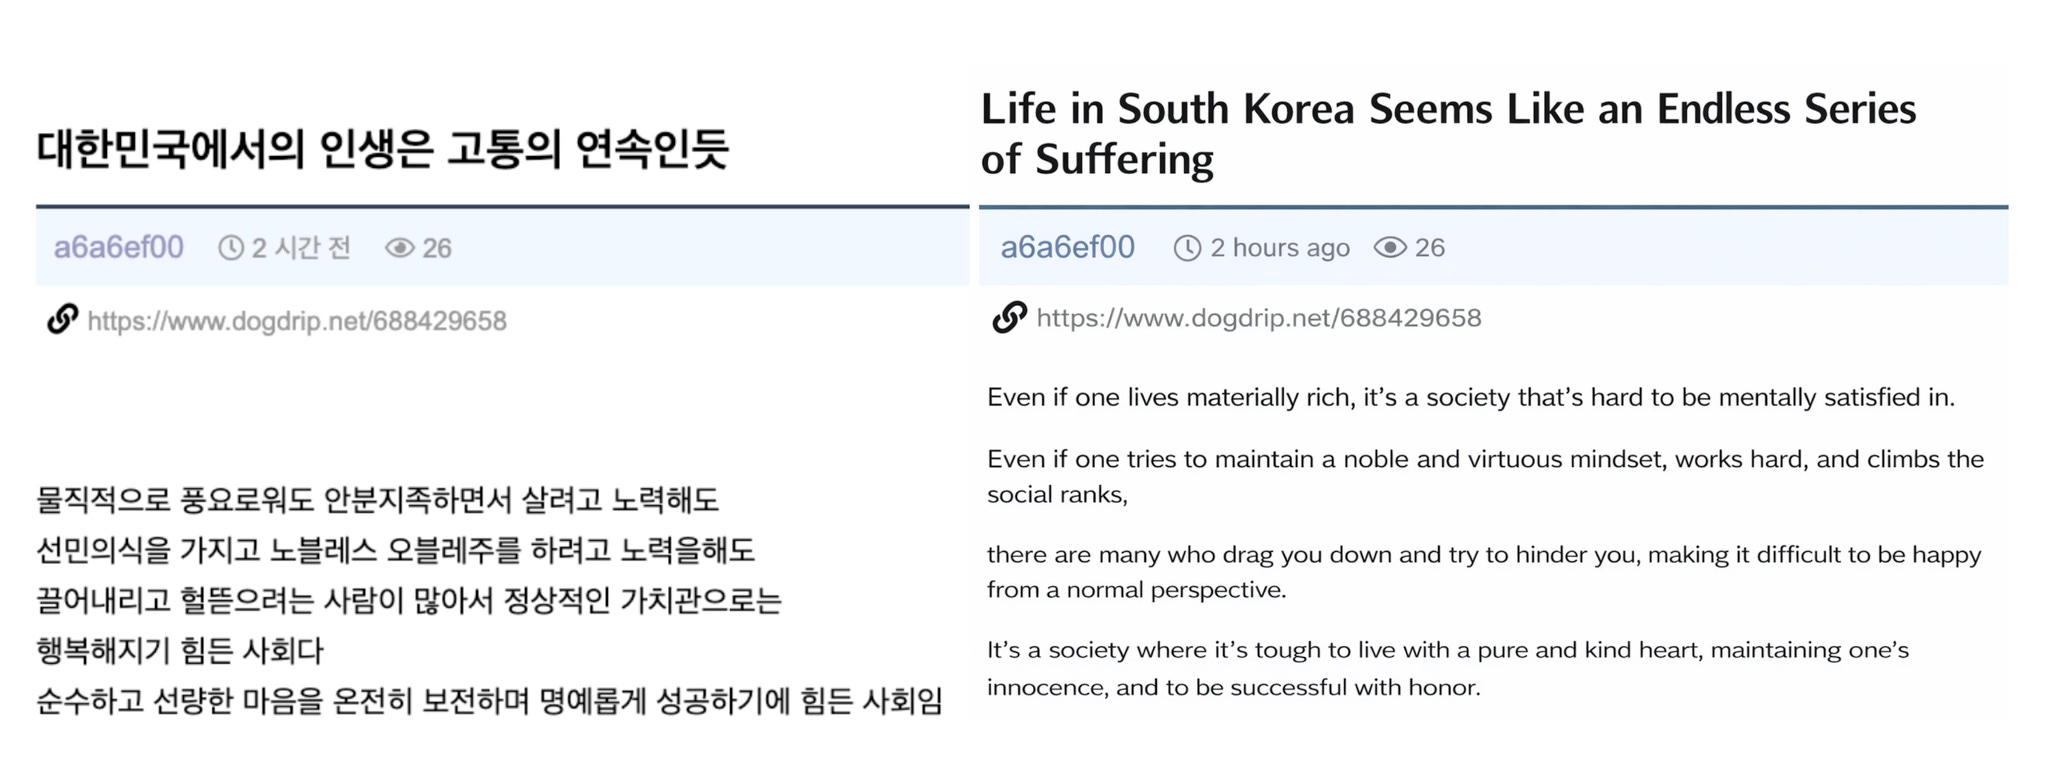
Each post has a title, body text, view count, and comment count. Looking at the number of posts by month, we see that DogDrip’s consultation board is going through a slow death:
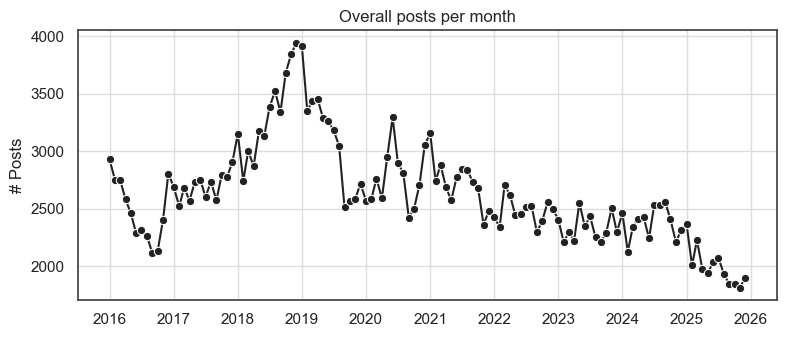
Peak activity hit around 2019-2020 with ~4,000 posts per month. By 2025, it's down to ~1,500—a 60% collapse. This would be consistent with younger users migrating to Discord. As a result, the consultation board feels like a relic of Korea's early-2010s forum culture.
What Do Korean Men Talk About?
The first step to understand their posts is to build a quick taxonomy. I first start with a keyword-based classifier. If a post mentions “결혼” (marriage), “남편” (husband), or “시댁” (in-laws), it’s tagged marriage/family. “여친” (girlfriend) → romance/dating. “코인” (coin), “주식” (stocks) → investing/crypto. And so on.
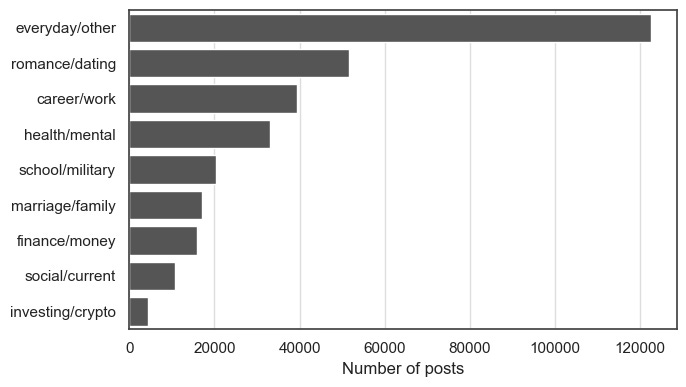
About 40% of posts fall under everyday/other, followed by romance/dating (16%), career/work (13%), and health/mental (11%). When we look at the distribution across time, we find that only one category has grown over time: marriage/family:
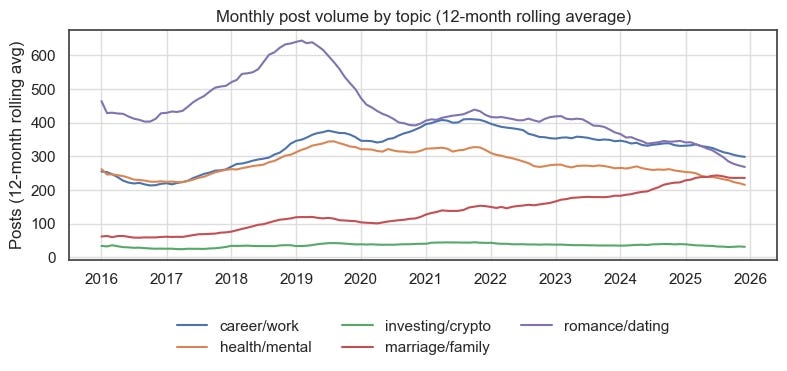
Marriage posts were rare in 2016 (~50/month), but by 2023 they'd tripled (~150/month). Meanwhile, romance/dating posts declined. One reason for this could be that younger users left for TikTok, while older users stayed because no other platform offers this level of anonymity for marital problems. The board essentially aged with its users.
Statistical Topic Models
As a brief aside: keyword tagging is clean but dumb. For example, “투자” (invest) matches both “I invested in Bitcoin” and “I invested emotionally in this relationship.” To discover what people actually mean, I tried Latent Dirichlet Allocation (LDA): a statistical model that treats each post as a mixture of hidden topics, then reverse-engineers those topics from word patterns.
The issue is that LDA is famously finicky and while it works great on academic papers (where topics are disciplines), it struggles with messy human language. Running it on 30,000 translated posts, I got 15 topics... most of which were incoherent. Topic 7’s top words: “really, know, friend, said, told.”
The Persistent Shadow of COVID
South Korea's COVID response was strict: multi-month "Level 2.5" restrictions in Seoul, capacity limits, remote work mandates. Did these lockdowns reshape what people worry about? To check, I counted posts explicitly mentioning COVID-related terms by month.
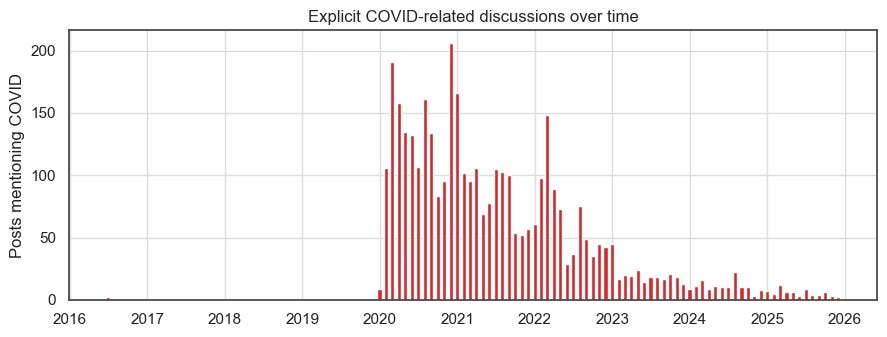
COVID mentions spike in mid-2020 and peak around early 2021 at roughly 200 posts per month, tracking Korea’s strictest social distancing waves. But the decay is slower than you’d expect. Korea lifted all major restrictions in 2023, yet COVID-related posts never fully disappear. They’re still trickling in at 5-10 per month through 2024 and into 2025.
The pandemic didn’t just come and go as a topic. It left a residue, whether that’s long COVID health anxiety, lingering social isolation, or job market scars from the lockdown years.
What Drives Views and Comments?
When someone writes a post on this board (as it’s specifically meant for consultation), he wants a a response. They’re putting a question out to strangers and hoping the crowd actually shows up. So it matters which posts get attention and which get ignored, because that’s the market signal for what anonymous strangers are willing to help with.
It turns out that not all posts get equal attention. Median views is around 400 and median comments around 10, while top posts hit 900k views and 400 comments. What makes some posts blow up? As a simple test, I compare each topic’s share of total posts to its share of total views:
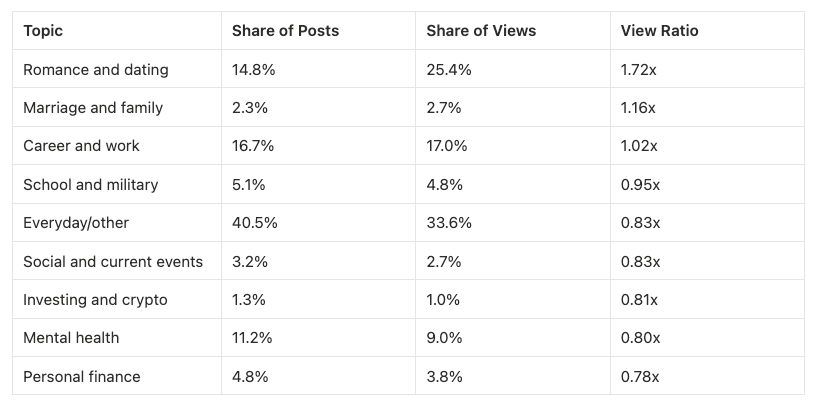
Romance posts earn 1.72 times their expected share of views. Nothing else is close. In contrast, mental health is the third most common topic by volume, but it draws only 80% of its expected views.1
Predicting Virality
Beyond topic-level averages, I wanted to know which words in the title predict whether a post blows up. The approach: take each post title, break it into individual words and word-pairs, and score each term by how distinctive it is. A word that appears in one title but rarely across the full dataset gets a high score; a word that appears everywhere gets a low score. (This scoring method is called TF-IDF, for term frequency-inverse document frequency.) We can then feed those scores into a logistic regression that predicts whether the post lands in the top 25% by views or comments.
Model 1: Title → high views. This is a title-only model. It can’t see the body text, only what shows up in the feed. That’s the point: it tells us what people click on before reading a single word of the actual post. The top predictive terms:
19 (age)
남친이 (my boyfriend)
여친이 (my girlfriend)
남친 (boyfriend)
여친 (girlfriend)
전여친 (ex-girlfriend)
Relationship words dominate. The number “19” (a Korean age that signals a young person, often in a sexual context) is the single strongest predictor of high views. Notably absent: anything about career, investing, or mental health.
Model 2: Title → high comments. Same setup, but predicting comments instead of views. The top terms shift:
남친 (boyfriend)
남친이 (my boyfriend)
남자들 (men)
결혼 (marriage)
남편이 (my husband)
연봉 (salary)
Relationship words still lead, but now marriage, husbands, and salary enter the picture. People click on “19-year-old girlfriend” posts out of curiosity, but they argue in posts about marriage and money.
Model 3: Title + body → high comments. What if the model can read the full post, not just the title? I ran a third model that includes the body text alongside the title. The top predictors barely change. The title carries most of the signal, which makes sense: on a board with thousands of posts, people decide whether to engage based on the title alone.
Why do they use online boards in the first place?
So far we've looked at what they post about and what gets attention. But there's a deeper question we keep skating around: why come to anonymous strangers at all, instead of a friend or a therapist?
There are two competing stories. The first is stigma cover: the topic is too embarrassing to bring up with people who know you, so you go where nobody knows your name. What the board sells you is anonymity. Call this the demand side, because it's about what posters need that their own social network can't provide.
The second is wisdom of the crowd: the topic is one where you want many strangers' reactions, not one friend's single opinion. Call this the supply side, because it's about what the board's audience uniquely offers. Both stories predict that people show up, but they differ in what motivates people to come to the board in the first place.
In economics, the textbook way to separate these is to find a shock that hits one side without moving the other. We're going to do something similar using the launch of ChatGPT in November 2022 with a substantial Korean-language quality jump when GPT-4 arrived on March 2023. In some sense, ChatGPT is a near-perfect substitute for an anonymous board on one dimension as it provides (near-)total anonymity. It's a terrible substitute on the other, as there is no crowd or plurality of human reactions. So if posters were really coming here for stigma cover, ChatGPT should have pulled them away. If they were coming for the crowd, ChatGPT shouldn't matter.2
To run the test, I sort each post into stigma tiers using Korean keywords.
High-stigma topics include depression, suicidal ideation, sexual problems, body image, financial shame, abuse, addiction, and social isolation.
Low-stigma topics include career moves, salary, investing, consumer purchases, and travel. (A middle tier covering relationships and family conflicts is set aside for clarity. Adding it back doesn’t change the picture.)
Each post gets the highest stigma tier it touches: a post mentioning both depression and salary is high-stigma.
The idea is that if ChatGPT substitutes for stigma cover, the high-stigma series should fall faster than the low-stigma series after November 2022. Let’s see what it looks like:
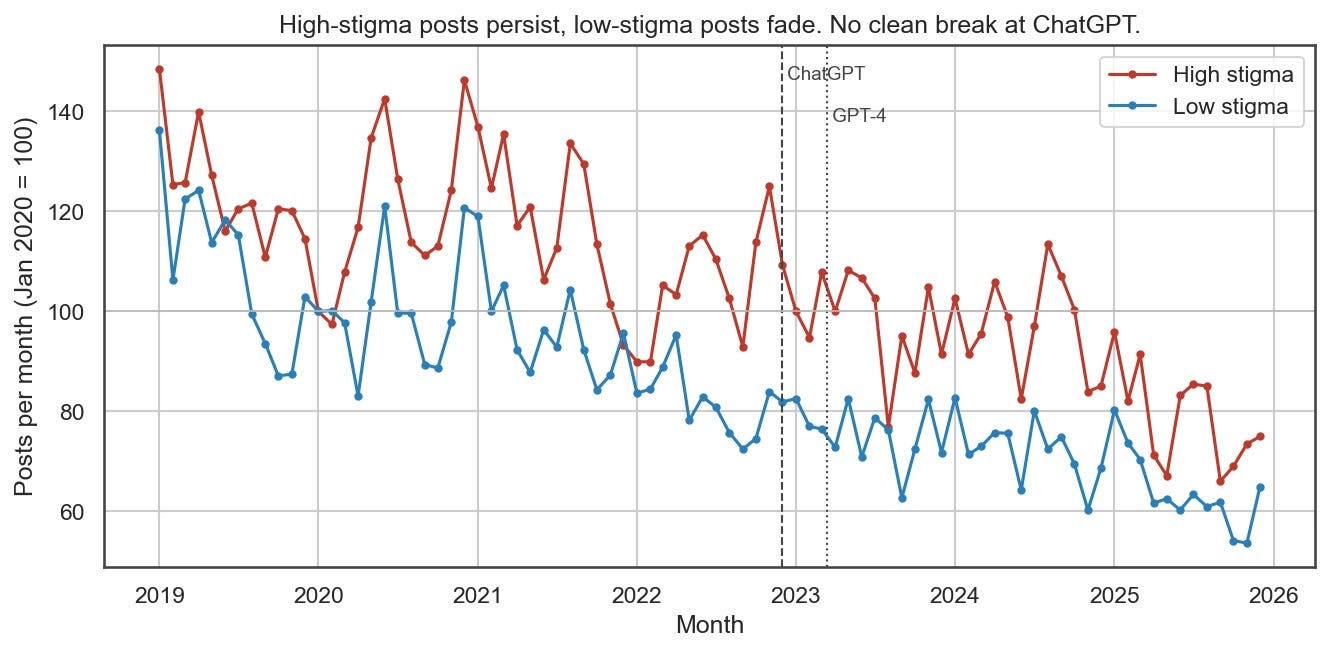
Here we plot monthly post counts by stigma tier, indexed to Jan 2020 = 100. Red = high stigma, blue = low stigma. Both decline through the window, consistent with the board's overall slow death. But the gap between them doesn't widen or shrink in any obvious way around the dashed (ChatGPT) or dotted (GPT-4) lines.
So it looks like ChatGPT didn't differentially eat the high-stigma posts. Compare this to what happened on a different forum during the same period:
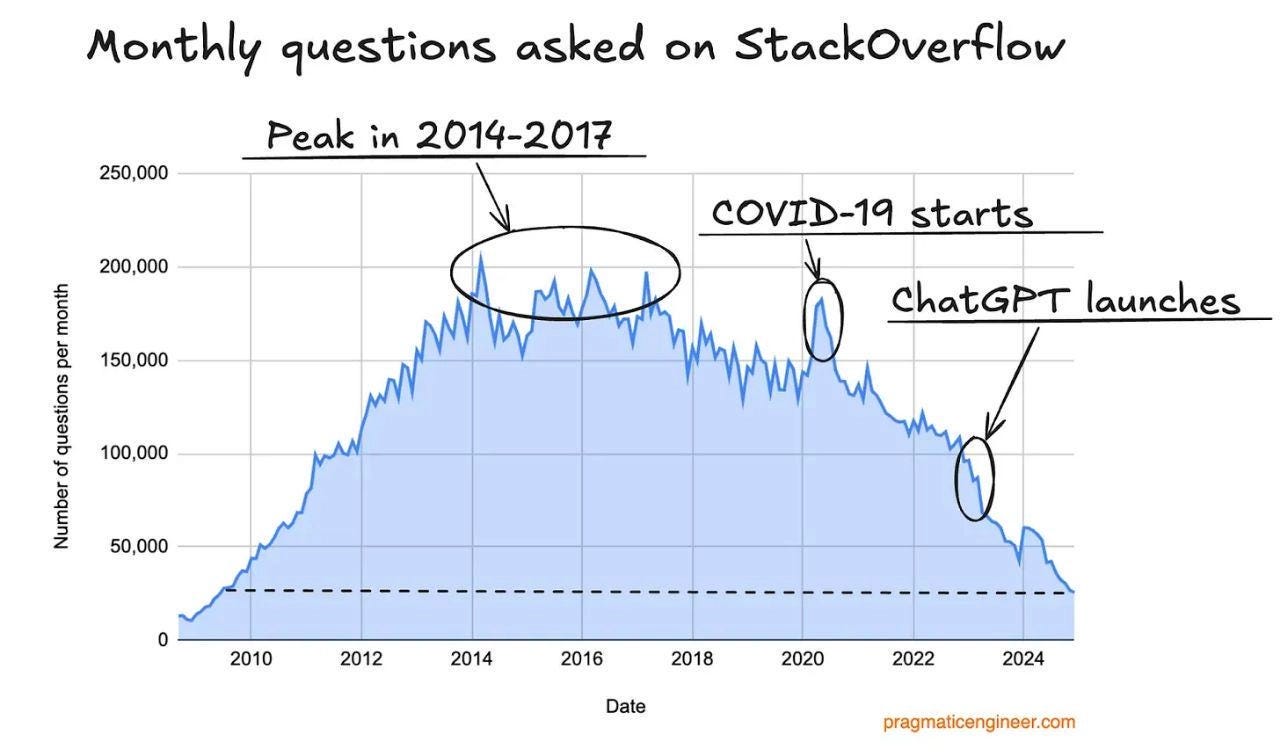
Stack Overflow, the canonical Q&A site for software engineers, fell off a cliff once ChatGPT launched. Monthly questions had been drifting down since their 2014–2017 peak, but the post-ChatGPT decline is more of a sharp, sustained collapse.
So the pattern for the Korean forum suggests that the reason posters keep showing up isn't anonymity, which ChatGPT also provides. Rather, it’s the experience of being witnessed by other humans, even strangers, who might react, disagree, judge, or pile on. It looks like the wisdom — or the folly — of he crowd is what these men were looking for all along.
Conclusion
Takeaways
Before ChatGPT, Korean men were already confessing to strangers at scale. The technology changed (forums to AI), but the need for non-judgmental advice didn’t. The questions are the same ones people now ask chatbots: Am I normal? Should I quit? Is this relationship over? How much should I be earning?
What people post about and what the crowd reads are different. Career and mental health dominate the demand for advice. Romance dominates the supply of attention.
Further Research Questions
I scraped post titles and bodies but not comments. The comments are where the actual advice lives, and where the arguments happen. Scraping those would let us measure the supply side directly: not just who clicks, but who responds and what they say.
The board’s 82% male skew means we’re seeing one side of the story. Women’s anonymous forums exist in Korea (e.g., female-dominated communities on Nate Pann). A comparison would reveal whether the demand/supply asymmetry is gendered or universal.
Keyword classification is transparent but crude. A proper embedding-based approach (e.g., using a Korean-language BERT model) could capture topics that keywords miss, especially the 40% that fell into the catch-all bucket.
Translation flattens idioms. “답답하다” (feeling stuffy/frustrated) becomes generic “frustrated,” losing emotional texture. Working directly in Korean with Korean NLP tools would preserve more of the signal.
This is consistent with the finding from Berger and Milkman (2012) who find that high-arousal emotions (anger, anxiety, awe) drive sharing, while low-arousal emotions (sadness) suppress it.
One might object: isn’t ChatGPT itself a kind of crowd, trained on millions of human conversations? In a statistical sense, yes. But that crowd has been averaged into a single, smoothed voice. It doesn’t disagree with itself, pile on, or pick sides. In contrast, the board offers the live, plural version with discrete strangers replying in real time, some kind, some hostile, some bored.